


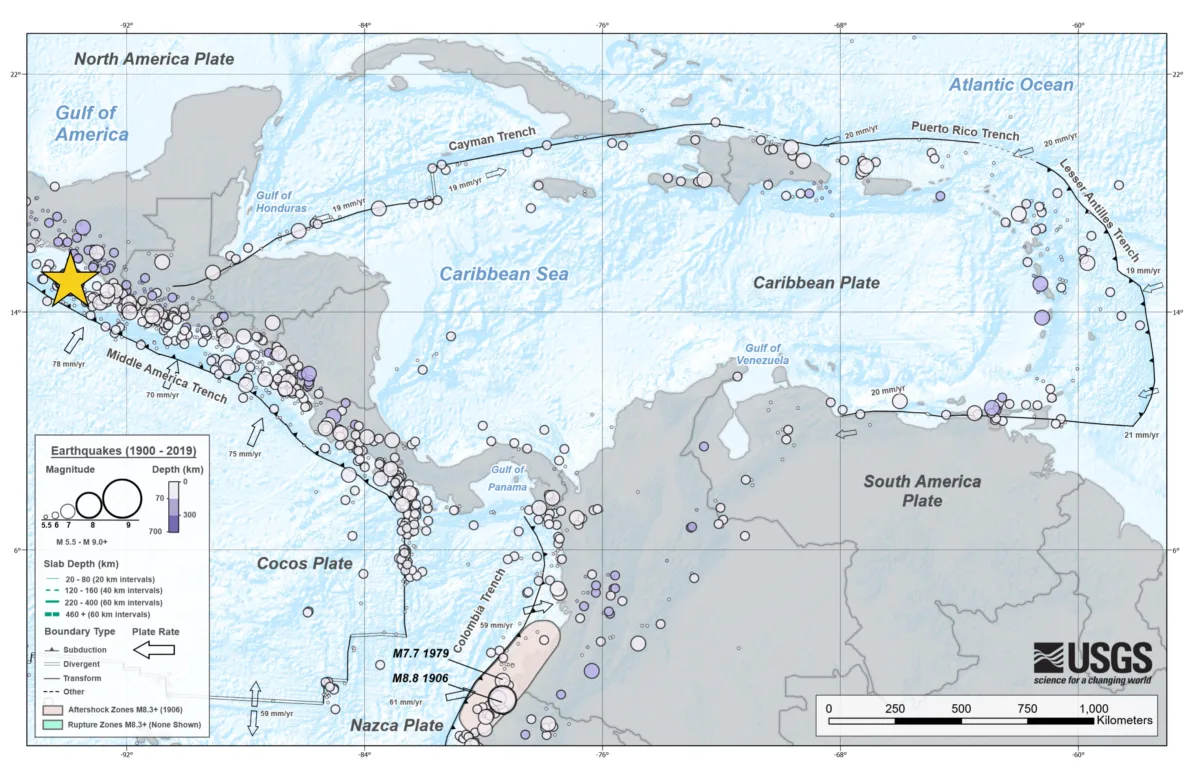
On July 18, 2026, a magnitude 7.3 earthquake struck Mexico’s west coast. The megathrust earthquake occurred offshore, where the Cocos tectonic plate subducts northeastward, beneath Mexico and Central America. The event was shallow, at only 20 kilometers depth — capable of producing a tsunami.
Yet, the resulting waves were relatively mild. Though shaking was felt as far away as Mexico City to the north, and throughout El Salvador to the south, news reports indicated no fatalities in spite of the event’s size and location.
This earthquake is not unusual, according to Marc Garcia, a postdoctoral researcher at the University of Texas, El Paso. “It struck… in a region that ranks among the most seismically active plate boundaries in the world,” he said. Past events of similar magnitude occurred in 1970 and 1993. “Given its thrust mechanism and shallow depth, the magnitude 7.3 [earthquake] more than likely ruptured the subduction interface itself,” he explained.
But a nearby region features much more complexity when it comes to earthquakes and tectonics. Consider the September 8, 2017 magnitude 8.2 Tehuantepec earthquake. This event, said Garcia, was an entirely different kind of earthquake. It ruptured with normal motion, occurring completely within the downgoing Cocos plate, where it bends as it sinks into the mantle. The earthquake broke the entire lithosphere, propagating along a 150-kilometer-long fault before triggering a secondary segment to the northeast.
In a new paper published in Seismological Research Letters, a team led by Garcia used a machine-learning assisted workflow to curate a high-resolution aftershock catalog for the 2017 event. The new catalog contains 11,374 relocated earthquakes, and reveals how machine-learning based algorithms can facilitate our understanding of tectonically complex environments.
The big quake
The 2017 Tehuantepec earthquake was the largest instrumentally recorded normal-faulting rupture in Mexico. It occurred in what’s known as the Tehuantepec seismic gap — a section of the subduction zone with no historical record of a large earthquake before now. Moreover, the earthquake struck near a complicated section of the subduction zone interface. Here, the Tehuantepec ridge — an old fracture zone — heads into the trench. Adding even more complexity: The event occurred near the intersection of the North American, Caribbean, and Cocos plates.
The permanent network maintained by the Servicio Sismológico Nacional captured the main event and thousands of aftershocks. A six-month temporary deployment following the September mainshock began recording vibrations on October 1, 2017. This NSF-funded deployment, called RAPID, was a collaboration among several institutions — the University of Texas at El Paso, Universidad Nacional Autónoma de México, Universidad Autónoma de Ciudad Juárez, and the Servicio Sismológico Nacional. Stations were hosted in schools and homes, and the data are available from the NSF National Geophysical Facility.
The complexity of the event and its tectonic setting present several challenges to curating an earthquake catalog, including high event rates, onshore and offshore seismicity, a lithosphere rife with faults, and sparse station coverage near the rupture itself. These challenges offer an opportunity for scientists to evaluate machine learning-based workflows. In other words, can seismology’s bespoke machine learning tools parse data from a complex region in a helpful way?
Pretrained tools
In seismology, machine-learning-based tools have become widely available over the last ten years or so. These specialized algorithms help tackle the massive amount of data generated by modern seismic networks. Such volumes are difficult to process using traditional methods, which often require manual review. On the other hand, after machine-learning methods are trained and validated, “they can process months of continuous data in house,” the authors wrote.
But are they universally helpful? These algorithms are trained on some subset of data. When applied to similar datasets, they exhibit comparable accuracy to human analysts. However, previous studies have shown that performance can diminish when applied elsewhere.
The 2017 Tehuantepec earthquake and its aftershock sequence — a normal faulting event set in a tectonically tricky subduction zone setting — already have an official earthquake catalog produced by the Servicio Sismológico Nacional. The earthquake sequence provides a test-case for Garcia and colleagues to explore just how well machine-learning-based tools fare in such a situation.
Finding earthquakes
Whether using machine-learning or traditional techniques (or in this case a combination), a typical workflow for transforming raw seismic data into an earthquake catalog follows some general steps. The waveforms must be prepared, which often involves filtering unwanted noise from the signal. Then, phase picking commences, in which each waveform is analyzed for arrivals of P-waves and S-waves (and other phases as needed). In the third step, called phase association, the picks from different stations must be matched to each other, and to their earthquake source. This step provides a rough location of the earthquakes’ hypocenters.
At this point, things begin to loop back on themselves. The earthquakes’ absolute locations are initially determined using a one-dimensional seismic velocity model — usually a fairly simple one. But the earthquakes can be inverted for a regionally specific seismic velocity model, which in turn improves their locations. Then, another round of phase association might be called for.
To refine earthquake locations even further requires another step — relative relocation. If earthquakes nucleate near one another, their seismic waves travel to a given sensor along almost the same path. If an earthquake is further away from this hypothetical pair, its waves will take more time to arrive. The relative time difference can be measured very precisely and converted into relative location. In other words, relative location can tell you how the earthquakes are distributed relative to one another, which illuminates structures responsible for the ruptures.
The terminal task is to finalize your catalog by assigning each event a magnitude, but we’ll get to that momentarily, as it involves some additional calculations.
A combination approach
In Garcia’s study, two of the above-mentioned tasks were carried out by machine-learning-based algorithms.
Filtering wasn’t fancy. Garcia filtered the data to suppress long-period noise as a way to reduce signals from distant, moderate-to-large magnitude earthquakes (known as teleseismic events). In this way, the team could focus on smaller, local earthquakes.
The first machine-learning-based tool the team used was PhaseNet, a pretrained deep neural network that outputs probability distributions for P-waves, S-waves and noise from three-component data. It’s a phase-picker with a reputation for doing good job.
Garcia selected the machine-learning framework GaMMA — a probabilistic phase association algorithm based on Bayesian Gaussian mixture models — for the phase association step. GaMMA treats the task of phase association as an unsupervised clustering problem, no training needed. For this step, the team excluded events deeper than 300 kilometers or located more than 500 kilometers from any station.
Then, traditional methods take over. HypoInverse takes the GaMMA-associated events and relocates them using the Servicio Sismológico Nacional national one-dimensional velocity model. VELEST then inverts the data — in this case, a selection of 4,500 well-constrained earthquakes — using the initial one-dimensional velocity model as a starting point. The result: an updated one-dimensional velocity model that’s used as the reference velocity structure for all subsequent steps, including another round of HypoInverse locations.
Of 18,000 events, 11,374 met the criteria for HypoDD, which relocates earthquakes, substantially improving our understanding of how the earthquakes are distributed relative to one another.
But there’s one more step — finalizing the catalog by calculating magnitude.
Magnitude shift
GaMMA, that second machine-learning tool, also estimates magnitudes. However, in this study, these estimates were off for events with higher magnitudes. For instance, the 2018 magnitude 7.2 Pinotepa earthquake came back with a magnitude of 4.72, shifted by more than 2 units of magnitude.
To solve this problem, Garcia and colleagues had to recalibrate magnitudes for all earthquakes. Comparing the recalibrated catalog with the Servicio Sismológico Nacional catalog showed an agreement within about 0.2 magnitude units for most events. And, the magnitude of completeness for the recalibrated catalog was about 3.5, a subtle but important improvement compared to 3.8 for the Servicio Sismológico Nacional catalog.
Catalog performance
Magnitude estimates aside, how did the combination of machine-learning and traditional tools do? To answer this question, the team compared phase picks and event locations with the Servicio Sismológico Nacional’s for October of 2017. During this month, both the permanent and temporary networks were operational. October also had the highest aftershock rate, which meant plenty of seismicity to study.
PhaseNet— the phase picker — performed well for small to moderate events at distances less than 150 kilometers. In fact, distance was more important than magnitude. The same was not true for large-magnitude earthquakes. For these events, the automated workflow produced fewer per-station picks, so the team manually reviewed and repicked all 45 events with magnitude 5.0 or greater.
GaMMA — the phase association tool — filters out picks that could not be associated with any event. For small-magnitude earthquakes, waveforms attenuate rapidly, which means that fewer stations record their arrivals. GaMMA requires 6 picks to define an event, so events with fewer picks were rejected. A human analyst can include events that an automated associator — like GaMMA — rejects. For instance, an analyst may accept lower signal-to-noise arrivals, or allow sparser station coverage (translation: fewer picks per event). “That flexibility comes at the cost of reproducibility and scalability,” the authors note.
For event location metrics, Garcia and colleagues compared both the HypoInverse (16,076 locations) and HypoDD (11,374 relative relocations) catalogs against the Servicio Sismológico Nacional reference catalog for the entirety of the study period. In particular, the HypoDD-relocated hypocenters are more tightly clustered along the rupture zone, with less horizontal scatter. Three distinct zones of seismicity emerge: shallow upper-plate seismicity associated with a magnitude 6.1 aftershock; intraslab seismicity within the subducting Cocos slab associated with the mainshock; and deep seismicity at the plate boundary interface.
Incorporating RAPID
Another major difference between the Servicio Sismológico Nacional reference catalog and the dataset presented in this study is the incorporation of the RAPID dataset. The team found that of the 16,076 event locations (the HypoInverse catalog) spanning September 2017 to March 2018, 7,165 events match the Servicio Sismológico Nacional events within ±15 seconds and ±25 kilometers. Moreover, 8,911 events are new, mostly concentrated within the onshore aftershock zone of the magnitude 6.1 aftershock.
In particular, the RAPID network, the authors note, caught earthquakes within the magnitude range of 2 to 3. The network resolves roughly five times as many events as the Servicio Sismológico Nacional network does.
But a real concern for any machine-learning catalog is whether those new events are real, or just “well-behaved artifacts.” The authors argue that the picks were internally consistent and did not reference any external catalog, which suggests that they are physically real.
Validate first, then trust
Before being trusted across magnitudes and distances in a new location, pretrained pickers like PhaseNet should be validated, wrote Gracia and colleagues, pointing to the missed picks for large magnitude earthquakes and the need to manually review these events. This suggests that machine-learning workflows cannot be casually applied to the task of constructing earthquake catalogs. GaMMA’s first-pass magnitudes also required adjustment.
Nevertheless, the new catalog is the most comprehensive for this earthquake sequence, and the first to incorporate data from the RAPID deployment. And so, with validation against local benchmarks and integration with conventional location methods, PhaseNetand GaMMA, two machine-learning-based workflows, can indeed yield earthquake catalogs in complex environments.
This study used data available in the NSF NGF data archive.